 Tiny Online Tools

How to Extract Structured Data from a PDF Fast
How to Extract Structured Data from a PDF Fast
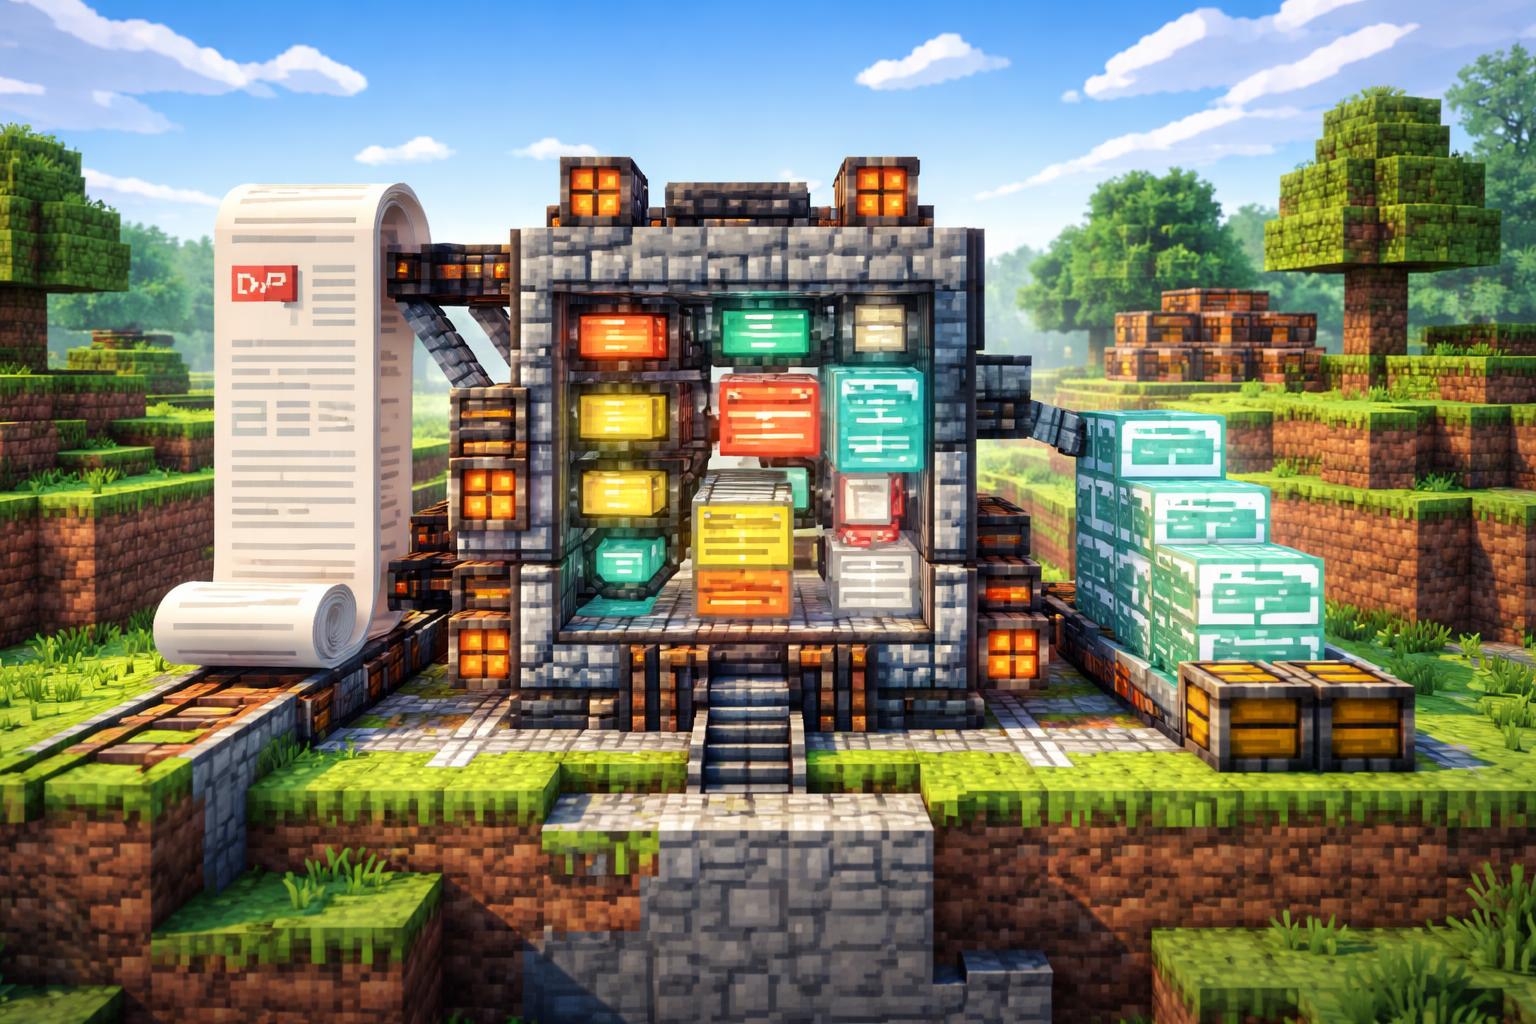
If you have ever stared at a PDF and wished it would just turn itself into something clean, useful, and editable, this tool is for you. The PDF Structured Data Extractor turns a PDF into structured JSON, including headings, paragraphs, lists, tables, and images. It can use the PDF's tagged structure tree when available, or fall back to layout inference when it is not.
That matters because PDFs are great for sharing, but not always great for working with. A document that looks polished to the eye can still be awkward to reuse in apps, scripts, audits, content pipelines, or data analysis. The PDF Structured Data Extractor helps bridge that gap by giving you machine-friendly output instead of forcing you to copy and paste your way through a document.
Why structured extraction is such a big deal
Not every PDF is the same. Some are neatly tagged. Some are scanned. Some are generated from design software with a clear reading order, and some are full of nested columns, tables, and visual quirks. A good extractor needs to interpret those differences without losing the meaning of the page.
That is where the PDF Structured Data Extractor shines. Instead of flattening everything into a wall of text, it organizes content into real structure. That makes it much easier to:
- feed document content into a script or app
- preserve headings and reading order
- capture lists and tables more cleanly
- inspect content before building automation around it
- transform a PDF into downstream formats for reporting or analysis
Practical ways to use it
1) Convert reports into reusable JSON
If you work with recurring reports, the extractor can turn each PDF into a structured dataset. That is useful when you want to index documents, summarize sections, or pass content into another workflow without manually retyping it.
2) Preserve document hierarchy
Headings matter. So do lists. So do tables. If you flatten a PDF too early, you lose context. This tool is built to keep the hierarchy intact so the result is closer to the way the document was actually organized.
3) Handle mixed-content documents
Many PDFs are not just text. They contain images, tables, and layout-heavy sections. Structured extraction helps you separate the parts of the document so each one can be used appropriately.
4) Build smarter automation
If you are automating document workflows, structured output is often the difference between a brittle script and a dependable one. JSON is easier to validate, filter, and store than raw extracted text.
5) Pair it with inspection tools
When you need to understand more than just the visible content, combine this tool with PDF Hidden Data Inspector. If you only need links, use PDF Link Extractor. If the PDF contains attached files, PDF Embedded File Extractor is the better fit.
How to use the PDF Structured Data Extractor
Using the PDF Structured Data Extractor is straightforward:
- Open the tool.
- Upload or provide the PDF you want to analyze.
- Run the extraction.
- Review the JSON output for headings, paragraphs, lists, tables, and images.
- Copy the structured result into your workflow, app, or analysis pipeline.
If you need to compare visual content later, the PDF Image Extractor can help you pull embedded images directly from a PDF.
Tips for better results
- Use the original PDF when possible, not a screenshot or re-saved copy.
- If a PDF is tagged well, expect stronger structural output.
- For scanned files, check whether the layout still preserves the reading order you need.
- Validate the JSON before relying on it in production.
- Keep related tools in mind: tables, links, images, and hidden data are often better handled by specialized extractors.
When to choose this over plain text extraction
Plain text extraction is fine when you just need words. But when the structure matters, JSON is far more useful. If you want to know what belongs to a heading, what belongs to a list, and where a table begins and ends, the PDF Structured Data Extractor is the stronger choice.
And if your next question is, "What else is inside this file?" you already have a family of follow-up tools ready to go: PDF Table Extractor, PDF Hidden Data Inspector, and PDF Image Extractor.
Final thoughts
The best document tools do more than extract content; they preserve meaning. That is what makes the PDF Structured Data Extractor so valuable. It gives you a cleaner bridge from human-readable PDFs to machine-readable data, which makes automation easier, analysis faster, and downstream tools much more reliable.
If you work with PDFs regularly, this is one of those utilities that quickly becomes part of your standard toolbox.